Technology explained
From Photos to Explorable 3D Spaces: Understanding Gaussian Splatting
A photograph records a scene from one position. 3D reconstruction connects observations from different positions so we can move to a new viewpoint and look into the same space.
Imagine standing in a doorway. A chair hides part of the floor, and another corridor lies behind a corner. Take a step sideways: the chair shifts relative to the doorframe, and something that was hidden may become visible. These changing relationships help us understand space.
3D reconstruction aims to bring that way of looking to a screen. 3D Gaussian Splatting, usually shortened to 3DGS, is one way to represent and render a scene. Three questions make it easier to understand: how photographs connect, how the scene is represented, and how a new image is made.
The spatial clues between photographs
A photograph projects a three-dimensional space onto a flat image. An object that looks small might be small, or it might be far from the camera. Many different spatial arrangements can look similar in a single image. Photographs taken from other positions provide more evidence about the same scene.
A corner of a doorframe, a tabletop texture or a pattern on a wall may appear in several photographs. Corresponding observations and camera geometry help estimate camera positions, orientations and points in space. This process is commonly called Structure from Motion, or SfM.
This explains why more photographs do not automatically mean enough information. Turning the camera from one fixed position, or repeatedly taking the same view, may add little depth information. Moving between positions while keeping shared content in adjacent images helps connect those observations.
Camera relationships and an initial spatial structure provide a foundation. They are not yet a detailed scene that looks complete from every direction. The next step is a representation that can describe appearance and produce images from chosen viewpoints.
Representing a scene with soft elements
A conventional mesh describes surfaces with connected triangles and uses materials to form an image. 3DGS uses a different representation: many Gaussians in space, each with a position, shape, orientation, opacity and appearance information.
A Gaussian has an influence that falls away from its centre. A soft ellipsoid without a hard boundary is a useful mental picture. Viewed from a camera, it contributes a footprint that fades towards its edges.
During rendering, the footprints contribute colour according to their visibility and opacity. Together they form contours and detail. The enlarged group below helps explain their shapes, orientations and overlaps.
These elements are not placed individually by hand. Training compares rendered images with the input photographs and adjusts the representation to better match multiple observations. It progressively refines a description of the scene.
Move the viewpoint, change what is visible
Once a viewpoint is chosen, the system can calculate how scene elements project onto the screen. Moving sideways, closer or higher changes their projected positions, sizes and overlaps. The image is rendered again from that viewpoint.
Hold a finger in front of you and alternate between closing your left and right eye. Your finger appears to shift relative to the distant background. A camera moving through space observes a similar effect, called parallax. Objects at different depths shift by different amounts.
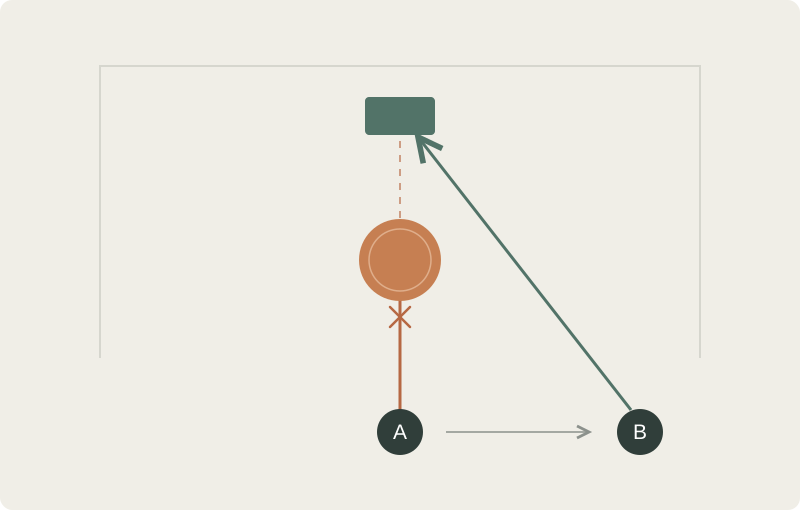
This differs from turning your head within a single panorama. A panorama typically records directions around one capture position; a 3D scene also lets the viewing position change. That freedom does not make every viewpoint equally reliable. Areas absent from the source images still lack observational evidence.
The result still depends on what was captured
If a table was photographed only from the front, a view from behind may reveal missing or unstable detail. If camera shake blurred the texture across several images, more training cannot guarantee recovery of information that was never clearly recorded. Quality depends on the evidence in the images, not just processing time.
Capture connected views around the subject before adding closer views of details you need to inspect. Aim for sharp images and steady lighting, and watch for people or moving objects. Glass, mirrors and large textureless surfaces need careful review. One attractive angle is not enough to judge the whole result.
Review a reconstruction by moving slowly along the intended viewing route. Look for stable contours, plausible occlusion and complete coverage of newly visible areas. Visual realism alone does not establish accurate dimensions or a collision surface. Measurement, walkable environments and engineering analysis each require additional data and validation.
From understanding to a first scene
For a creator, the sequence is straightforward: capture connected observations, establish spatial relationships, build a scene representation and inspect it from different positions. Each step supports the next. Understanding the sequence helps you decide whether a local problem calls for more photographs, a revised viewing route or further scene preparation.
MakeWorlds Studio organises creation around image input, reconstruction, inspection and scene preparation. For a first set of photographs, choose a stationary object you can walk around or a small, accessible space. Begin by learning to capture one coherent subject before moving to more complex scenes.